Disclosure: the Firecrawl links in this guide are affiliate links, so BoostStash may earn a commission if you sign up through them. I’ve kept the pricing and feature details tied to Firecrawl’s own documentation.
The slow part of finding clients isn’t writing the email. It’s the hour before that, when you search for businesses that fit, open their sites one by one, check whether they have the problem you solve and look for a way to contact them. That research is exactly what a small Python agent can do for you, and this guide shows how to build one.
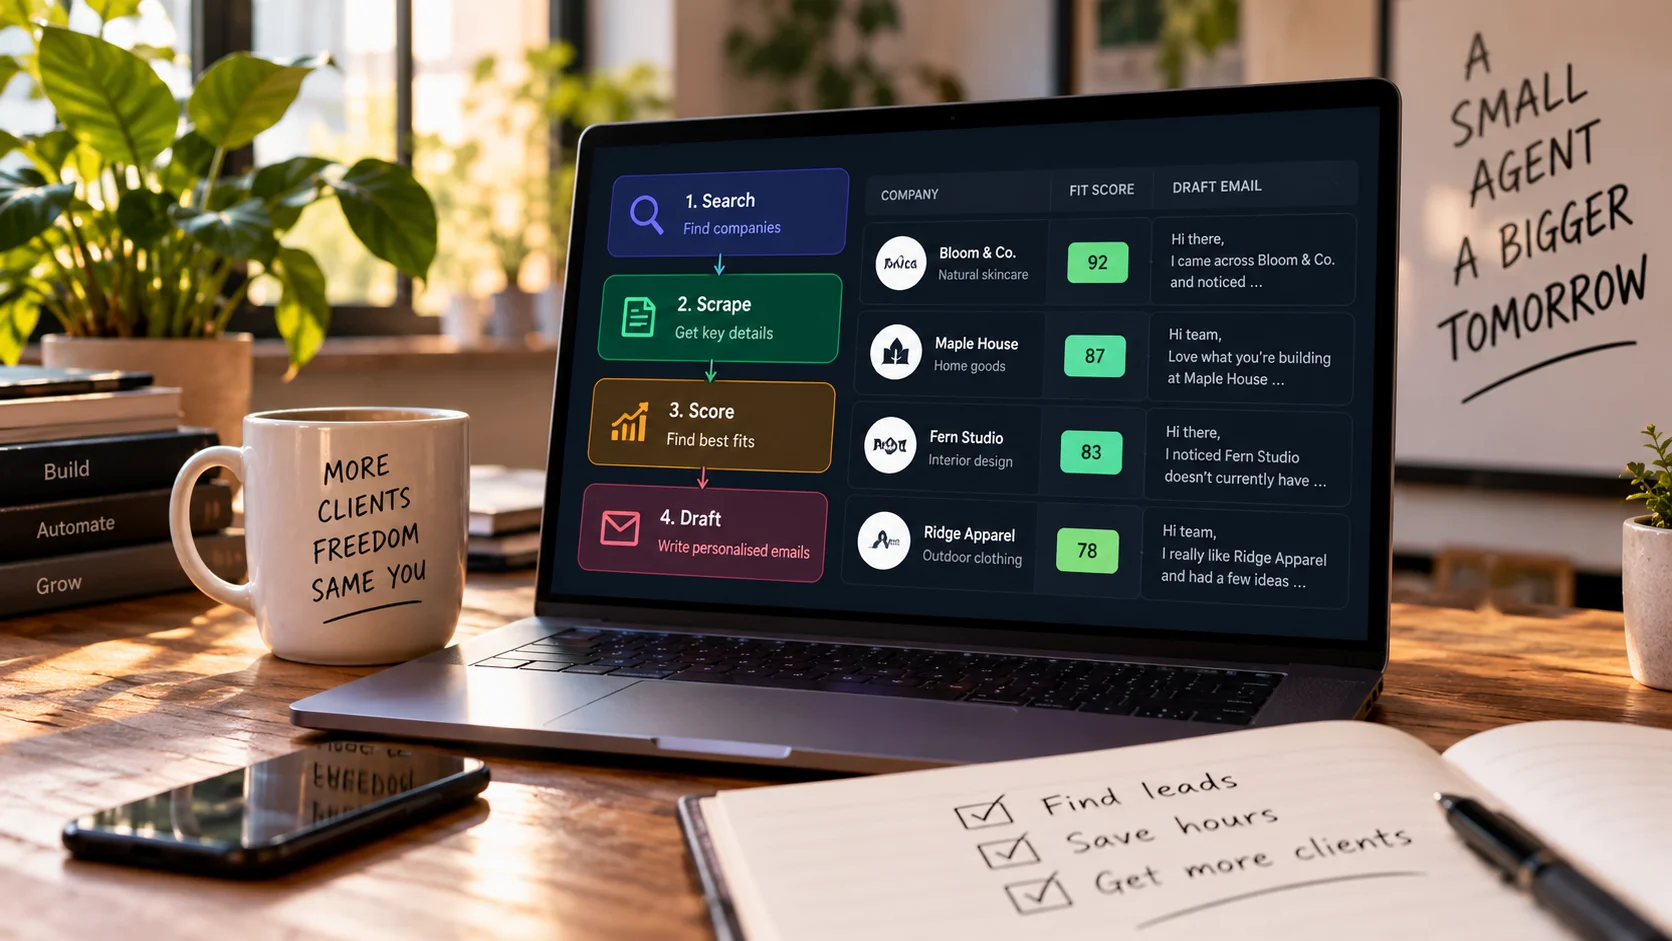
You will end up with a script of about 130 lines. It searches the web for companies that match your ideal client, pulls structured facts from each site using Firecrawl, has Claude score every lead, and writes a spreadsheet of the best ones with a draft email beside each. It never sends anything. That part stays with you.
If you sell a service to small businesses and spend your mornings on prospect research, this setup is worth an afternoon. If you want a tool that finds, writes and sends on its own, this isn’t it, and I’ll explain why that’s a feature.
This setup suits service sellers with a clear niche, and not much else
The agent works best when your ideal client has a problem you can see from the outside. A freelance email marketer can spot an online store with no signup form in seconds. A web designer can spot a site that loads badly on a phone. A bookkeeper can’t spot anything from a homepage, so the agent has little to qualify on.
It fits you if you sell a service to small businesses, you can describe your ideal client in a sentence, and you’re willing to read every lead before anything goes out. It’s a poor fit if you need thousands of leads a week, if your buyers are individuals rather than businesses, or if you want fully automated sending. For those cases, a dedicated sales platform or a managed outreach service will serve you better than a 130-line script.
The agent runs in six stages, and you own the last one
Each stage feeds the next, so you can build and test them one at a time.
- Define the ideal client and the signals that show a good fit.
- Discover candidate companies with Firecrawl’s search endpoint.
- Extract structured facts from each company’s site.
- Score every lead against your criteria with Claude.
- Draft a personalized email for the leads that score well.
- Run it on a schedule and write the results to a sheet or CRM. You review and send.
The script has no send function, on purpose. A model can misread a page, and a wrong first sentence in a cold email costs you that contact for good. Sending also carries legal obligations that belong to you, which the rules section below covers. Treat the output as a prepared shortlist that you approve line by line.
Stages 1 and 2: describe a client the agent can check, then let Firecrawl search for them
The agent can only qualify a lead on things it can see. “Companies that need better marketing” is invisible from a website. “Online stores with no email signup form” is visible in seconds.
Pick one niche and one offer, then list two or three signals that a public page can confirm. If you’re a freelance email marketer, your description might read: independent online stores selling physical products, roughly 5 to 50 staff, with no visible email signup or abandoned-cart messaging. Write it as a short paragraph, because the script drops it word for word into the scoring prompt. Add one or two disqualifiers too, such as marketplaces, franchises or companies outside the countries you can legally email.
Then install the two libraries.
pip install firecrawl-py anthropicFirecrawl’s search endpoint takes a query and returns web results in results.web, each with a URL, title and description. It can also scrape every result in the same call, which the docs describe as discovery and extraction in one step. The script keeps the two apart so you can drop duplicate domains and blocked companies before spending any extraction credits.
from firecrawl import Firecrawl

fc = Firecrawl(api_key="fc-YOUR_KEY")
results = fc.search("independent skincare brand online store about us", limit=10)
for item in results.web or []:
    print(item.url, item.title)
Search costs 2 credits per 10 results. Write queries that describe the page you want to land on rather than the type of company: “about us”, “our story” or “contact” plus your niche tends to surface pages that state facts. Search returns what its index returns, not a complete market list, so run several differently worded queries.
Get your Firecrawl API key
Firecrawl’s free plan includes 1,000 credits a month, which is enough to try the whole pipeline on a small test batch. Create a free account and keep the API key ready for the next stage.
Create a free Firecrawl account → Affiliate link. Your price does not change.Stage 3: a JSON schema makes every site come back with the same fields
Once you have a URL, Firecrawl’s scrape call can return structured data instead of raw page text. You request the json format as an object (the docs are explicit that the plain string “json” won’t work), give it a prompt and a JSON schema, and read the result from doc.json.
LEAD_SCHEMA = {
    "type": "object",
    "properties": {
        "company_name": {"type": "string"},
        "what_they_sell": {"type": "string"},
        "team_size_hint": {"type": "string"},
        "has_email_signup": {"type": "boolean"},
        "recent_launch_or_news": {"type": "string"},
        "public_business_email": {"type": "string"},
    },
}

doc = fc.scrape(
    url,
    formats=[{"type": "json", "prompt": "Extract business facts published on this page. Leave a field empty if the page does not state it.", "schema": LEAD_SCHEMA}],
    only_main_content=True,
)
lead = doc.json or {}
Keep the schema small and tied to your Stage 1 signals. Every extra field is another chance for a wrong answer, and the instruction to leave unstated fields empty matters, because language models fill gaps when you let them. For the email field, collect only an address the company publishes for business contact, such as a general info or hello address. Don’t let the agent guess address patterns.
JSON extraction uses more credits than a plain scrape, so read the credits table on Firecrawl’s pricing page before you size a run. Pages that need a click or a cookie banner dismissed can be handled with the scrape call’s actions option or the separate interact endpoint, both described in the Python docs.
Stages 4 and 5: Claude scores from the facts only, then drafts a short email for you to approve
The scoring step sends your ideal-client paragraph and the extracted facts to Claude and asks for a score, a one-sentence reason and one specific observation you could mention in an email.
def score(lead):
    prompt = (
        f"Ideal client: {ICP}\n\nCompany facts (from their own website):\n"
        f"{json.dumps(lead, indent=2)}\n\n"
        'Reply with JSON only: {"score": 0-10, "reason": "one sentence", '
        '"angle": "one specific observation we could mention"}. '
        "Base the score only on the facts given. If facts are missing, score lower."
    )
    try:
        return json.loads(ask_claude(prompt, max_tokens=300))
    except json.JSONDecodeError:
        return {"score": 0, "reason": "unparseable", "angle": ""}
Two details do most of the work. The model sees only the extracted facts, not the open web, so it has nothing to embellish. And missing information lowers the score instead of being guessed, which keeps thin pages out of your shortlist. If the reply isn’t valid JSON, the lead scores zero rather than crashing the run.
The reason field is your audit trail. On your first run, lower the threshold, read twenty leads including the low scorers, and adjust the Stage 1 paragraph until the scores match your own judgment. The script uses one MODEL constant for scoring and drafting. If you want a smaller, cheaper model for scoring, add a second constant and pass it into the scoring call.
For leads that clear your threshold, a second call writes a short first email built around that observation. The constraints in the prompt matter more than the model: under 90 words, one observation, one low-pressure question, no invented facts and no claims of past contact.
def draft_email(lead, angle):
    prompt = (
        "Write a plain-text first email, under 90 words, from a freelance "
        "email marketer to this company. Mention this observation naturally: "
        f"{angle}\nCompany: {lead.get('company_name')}\n"
        "Do not invent facts, claims or past contact. End with one low-pressure question."
    )
    return ask_claude(prompt)
Every row in the output spreadsheet carries the source URL, the score, the reason and a status column that starts as needs_human_review. My recommendation is to check three things on each row.
- Open the page and confirm the observation is true.
- Confirm your offer fits what the company sells.
- Rewrite the first sentence in your own voice if it sounds like a template.
Approved emails go out from your normal email account or sequencing tool, not from this script. Keeping sending separate also means one mistake in the agent can never reach a stranger’s inbox on its own.
Stage 6: run it weekly, keep a do-not-contact list, and copy the full script
Once a manual run produces a shortlist you would actually email, put it on a schedule. A weekly cron job, a scheduled GitHub Action or any task scheduler will do. The script reads a plain text file called do_not_contact.txt, one domain per line, and skips anything on it. Add every company that opts out, every existing client and every competitor, and the agent won’t surface them again.
The output is a CSV, so it imports into Google Sheets or most CRMs directly. Add a column for the outcome (replied, meeting booked, no response) and review it monthly. The scores that predicted replies tell you how to rewrite your Stage 1 paragraph.
Firecrawl’s docs also list a monitor endpoint and a change-tracking format that could flag when a target site changes, for example after a new product launch. I haven’t covered them here, so read the docs before building on them.
Save the script below as leads_agent.py, set FIRECRAWL_API_KEY and ANTHROPIC_API_KEY in your environment, edit ICP and QUERIES, and run python leads_agent.py.
import csv
import json
import os
from urllib.parse import urlparse

from anthropic import Anthropic
from firecrawl import Firecrawl

fc = Firecrawl(api_key=os.environ["FIRECRAWL_API_KEY"])
llm = Anthropic()  # reads ANTHROPIC_API_KEY
MODEL = "claude-sonnet-5-5"

ICP = (
    "Independent online stores selling physical products, roughly 5 to 50 staff, "
    "with no visible email signup or abandoned-cart messaging on the site."
)

QUERIES = [
    "independent skincare brand online store about us",
    "small batch coffee roaster online shop contact",
]

LEAD_SCHEMA = {
    "type": "object",
    "properties": {
        "company_name": {"type": "string"},
        "what_they_sell": {"type": "string"},
        "team_size_hint": {"type": "string"},
        "has_email_signup": {"type": "boolean"},
        "recent_launch_or_news": {"type": "string"},
        "public_business_email": {"type": "string"},
    },
}


def load_blocklist(path="do_not_contact.txt"):
    if not os.path.exists(path):
        return set()
    with open(path) as f:
        return {line.strip().lower() for line in f if line.strip()}


def discover(queries, per_query=10):
    """Search the web and keep one URL per domain."""
    found = {}
    for q in queries:
        results = fc.search(q, limit=per_query)
        for item in results.web or []:
            domain = urlparse(item.url).netloc.lower()
            found.setdefault(domain, item.url)
    return found


def extract(url):
    """Pull structured facts from one page using Firecrawl's JSON format."""
    doc = fc.scrape(
        url,
        formats=[{
            "type": "json",
            "prompt": "Extract business facts that are published on this page. "
                      "Leave a field empty if the page does not state it.",
            "schema": LEAD_SCHEMA,
        }],
        only_main_content=True,
    )
    return doc.json or {}


def ask_claude(prompt, max_tokens=600):
    msg = llm.messages.create(
        model=MODEL,
        max_tokens=max_tokens,
        messages=[{"role": "user", "content": prompt}],
    )
    return msg.content[0].text


def score(lead):
    prompt = (
        f"Ideal client: {ICP}\n\nCompany facts (from their own website):\n"
        f"{json.dumps(lead, indent=2)}\n\n"
        'Reply with JSON only: {"score": 0-10, "reason": "one sentence", '
        '"angle": "one specific observation we could mention"}. '
        "Base the score only on the facts given. If facts are missing, score lower."
    )
    try:
        return json.loads(ask_claude(prompt, max_tokens=300))
    except json.JSONDecodeError:
        return {"score": 0, "reason": "unparseable", "angle": ""}


def draft_email(lead, angle):
    prompt = (
        "Write a plain-text first email, under 90 words, from a freelance "
        "email marketer to this company. Mention this observation naturally: "
        f"{angle}\nCompany: {lead.get('company_name')}\n"
        "Do not invent facts, claims or past contact. End with one low-pressure question."
    )
    return ask_claude(prompt)


def run(min_score=7, out_path="leads_for_review.csv"):
    blocked = load_blocklist()
    rows = []
    for domain, url in discover(QUERIES).items():
        if domain in blocked:
            continue
        lead = extract(url)
        if not lead:
            continue
        verdict = score(lead)
        if verdict.get("score", 0) < min_score:
            continue
        rows.append({
            "domain": domain,
            "url": url,
            "company": lead.get("company_name", ""),
            "score": verdict["score"],
            "reason": verdict["reason"],
            "public_email": lead.get("public_business_email", ""),
            "draft": draft_email(lead, verdict.get("angle", "")),
            "status": "needs_human_review",
        })
    with open(out_path, "w", newline="") as f:
        w = csv.DictWriter(f, fieldnames=list(rows[0].keys()) if rows else ["domain"])
        w.writeheader()
        w.writerows(rows)
    print(f"{len(rows)} leads written to {out_path}")


if __name__ == "__main__":
run()Where a Firecrawl agent beats the other ways to find leads, and where it loses
This build isn't the only way to prospect, and for some people it isn't the best one. Here is how it compares with the three other routes I see freelancers take. I've compared the approaches rather than specific products, because prices and features in this category change often.
| Approach | Best for | Where it falls short | How you pay |
|---|---|---|---|
| Manual search and a spreadsheet | Under 20 leads a week, or a niche you're still testing | Slow, and the quality drops when you're tired | Your time |
| This Firecrawl and Claude agent This guide | A niche where fit is visible on the company's own site | Finds only what sits on public pages, and extraction can be wrong | Firecrawl credits plus model usage |
| Contact-database platforms | Volume, and filtering by job title or company size | You filter on database fields, not on what the site shows | Usually a subscription |
| A done-for-you outreach service | No time to run any of it | Least control over who gets contacted and what's said | Retainer or per-result fee |
The agent's real advantage is the qualification step. A database can tell you a store has 20 employees. It can't tell you the store has no email signup form this week. If your offer depends on something visible on the site, this build answers a question the other routes can't.
Its weakness is the mirror image. It won't give you a verified email address, and it won't scale to thousands of leads a week without you thinking harder about cost. If your pitch depends on job titles or company revenue, start with a database and use the agent as a second filter.
What it costs: the free plan covers testing, and one formula sizes everything after that
Firecrawl bills in credits, and different endpoints use different amounts. These are the plan allowances in Firecrawl's billing docs.
| Plan | Monthly credits | Concurrent browsers |
|---|---|---|
| Free | 1,000 | 2 |
| Hobby | 5,000 | 5 |
| Standard | 100,000 | 50 |
Search costs 2 credits per 10 results, according to Firecrawl's pricing page. A basic scrape costs 1 credit per page according to a third-party pricing index, and the pricing page says advanced options such as the JSON format cost extra. Dollar prices change often, so read the live pricing page before you budget.
Search credits + (pages scraped × credits per page, JSON surcharge included). Five queries at 10 results each cost 10 search credits. Scrape 20 pages on your first run, check the usage figures in your Firecrawl dashboard to see your real cost per page, and multiply from there.
Two billing details catch people out. Plan credits expire at the end of each month, while auto-recharge credits roll over. And Firecrawl says it doesn't offer a general pay-per-use plan, so going past the free allowance means choosing a monthly tier.
My suggestion: stay on the free plan until a test batch gives you a shortlist you would email. Then pick the smallest tier that covers one weekly run, and compare the Firecrawl plans once you know your real credit cost per lead.
Firecrawl is also open source under AGPL-3.0 and can be self-hosted. Check the repository's README for what the self-hosted version includes, and read the license if you plan to modify it and run it as a service, because AGPL requires you to share those modifications.
Rules that keep the agent legal and your emails out of spam folders
I'm not a lawyer, and the rules differ by country, so treat this as a list of questions to settle before you send anything.
- Collect business information, not personal profiles. Stay with what a company publishes about itself. Skip social networks and anything behind a login, because their terms usually forbid automated collection, and check each site's terms and robots.txt before you include it. You are responsible for what you scrape.
- Know the email law where your recipients live. In the US, CAN-SPAM covers commercial email, business-to-business included. It requires accurate sender details, a physical postal address and a working opt-out that you honor promptly. The EU, UK and Canada have differently structured rules for unsolicited business email that can be stricter, and the details vary by country.
- Be who you are. Use your real name and business, a subject line that matches the content, and a simple way to opt out. Add every opt-out to
do_not_contact.txtthe same day. - Keep a source record. Each CSV row stores the URL the facts came from, so you can answer a recipient who asks where you found their details.
- Protect your sending reputation. Send from a domain you control with SPF, DKIM and DMARC configured, and start with small batches. A sudden burst of cold email from a new domain is a common way to end up in spam.
Firecrawl states that it is SOC 2 Type II compliant and offers a data processing agreement for GDPR. Those are the company's own claims, and they cover Firecrawl's service. They don't cover how you use the data afterward.
My recommendation: build the research half, keep the sending half manual
If your clients are small businesses and your offer depends on something visible on their website, this agent is a good use of an afternoon. It turns a morning of tab-hopping into a shortlist with a reason attached to each row. What it can't do is make your offer credible or write the sentence that earns a reply. Both depend on how clearly you can say who you help and what changes for them, which is why Stage 1 deserves more of your time than the code does.
If you're ready to try it, open a free Firecrawl account, run the script on twenty pages and read every lead before you change anything. The free plan covers that test, and what you learn will tell you whether a paid tier is worth it.
Build your lead research agent today
Open a free Firecrawl account, run the script on twenty pages and read every lead before you change anything. No credit card is needed to test.
Try Firecrawl free → Affiliate link. BoostStash may earn a commission if you sign up.Questions people ask before building this
Do I need a paid plan to try it?
No. The free plan includes 1,000 credits a month, which is enough for a first batch of about twenty pages if you keep the query count low. Start with Firecrawl's free plan.
Can I use a different AI model?
Yes, but only the ask_claude function talks to the model. The script uses Anthropic's client, so another provider means rewriting that one function. The MODEL constant only changes the Claude model.
What happens if a page fails to load?
The script skips pages that return no extracted data, but it doesn't wrap the scrape call in error handling. A failed request could stop the run, so add a try/except around extract(url) before you schedule it.